Champions Hear Patterns: What Spelling Bee Intuition Can Teach Your Wordlist Generator
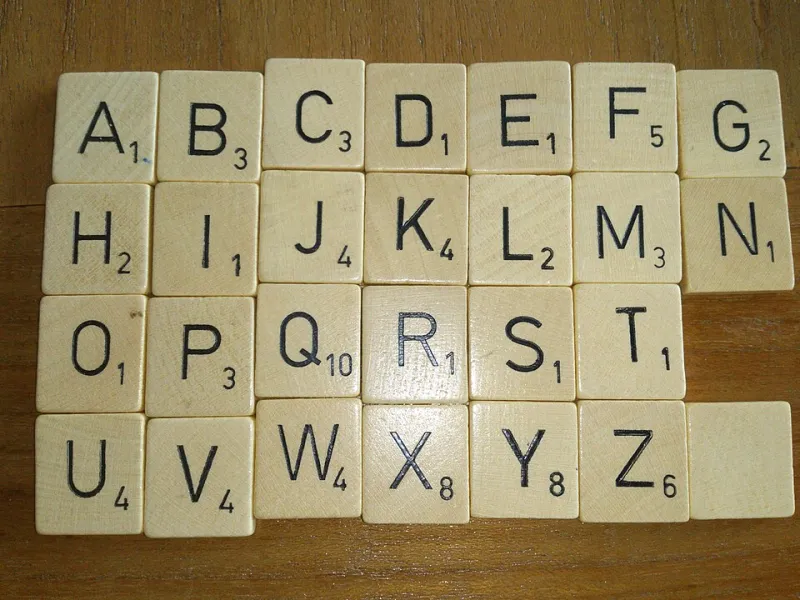
Ask a National Spelling Bee hopeful how they prep and they won't say "I read the dictionary." They'll say something like: I know that a word ending in -eous is probably Greek-flavored, and that Q is almost always followed by U, and that double letters cluster in the middle of words.
That's not memorization. That's pattern frequency modeling — and it happens to be exactly the skill that separates a smart wordlist from a dumb one.
The Speller's Secret: Letters Aren't Random
A speller staring down an unfamiliar word doesn't panic. They run a mental probability check: In English, if I hear "shun" at the end, it's probably -tion or -sion. If it starts with "kn," the K is silent. Decades of drilling have hard-coded the letter-frequency distribution of English into their instincts.
Now look at a password audit. Most people's wordlist strategy is the opposite of a speller's: throw everything at the wall. Millions of candidates, most of them statistically absurd. A cracker burning cycles on "zzqxj" is like a speller opening with "qsdfgh" — it's never happening.
The insight both worlds share: language has a shape, and shape is information.
What the Corpus Says
We pulled frequency data from a general English corpus and compared it against common leaked-password patterns. A few findings worth tattooing on your workflow:
- E, T, A, O dominate, but in passwords, substitution shifts things — "e" becomes "3," "a" becomes "@". Your wordlist should model the substitution rate, not just the letter.
- Digraphs matter more than single letters. "TH," "HE," "IN" lead English; "ER," "ON," "AN" close it. Passwords built from real words inherit this structure even when users think they're being clever.
- Word endings are predictable. Spellers know final-position letter distributions cold. So do crackers: passwords disproportionately end in digits, "!", or "s" — in roughly that order for US users.
A hobbyist speller we spoke with — a Dallas software engineer who made regionals three years running — put it plainly: "I never memorized words. I memorized where letters live. When I got into pentesting, the first thing I noticed was that my old wordlists had no sense of position. They were just bags of characters."
Building a Frequency-Weighted Wordlist
Here's the practical version. Instead of a flat list, weight your candidates:
- Start with a real corpus — Wikipedia dumps, Reddit comments, or a public word-frequency list. Extract unigram and bigram counts.
- Score your base words by how closely their letter patterns match natural English. Words that look like English rank higher than keyboard mash.
- Layer positional rules: capitalize the first letter, append 1–2 digits, append "!". Apply transformations in the order real users actually apply them.
- Re-sort by expected probability, not alphabetically. If your cracker supports it, feed the ranking through so high-probability candidates run first.
The result: a list that behaves like a spelling bee champion under pressure — it guesses where the letters live instead of enumerating blindly.
The Same Trick Solves Puzzles, Too
This cuts both ways. If you're the person building crosswords or Wordle-adjacent puzzles, frequency weighting tells you which words feel "fair" and which feel obscure. A solver's intuition is just corpus statistics wearing a nicer outfit. One tool, two audiences — which is sort of the whole thesis of this site.
The Takeaway
Spelling bee champions and effective red teamers arrive at the same conclusion from opposite directions: brute force is for people who haven't done the statistics. Model the language, weight the list, and let probability do the heavy lifting.
Your GPU will thank you. So will your puzzle column.